The central message. Being “In Control” means being prepared for errors and failures, rather than assuming they will never occur. Start with a thorough risk inventory and assessment, assign clear responsibility and put tested safeguards in place before an incident occurs. Secure primary systems remain essential; redundant, independent monitoring provides the last line of defence for detecting harmful physical changes and creating time to act, including during the power or connectivity failures it is designed to withstand. Keep the complete chain manageable and adaptable as global conditions and threats change: the aim is to prevent irreversible damage, not merely react faster.
Executive summary
Recent attacks on remotely managed refrigeration installations across Europe show how cyber incidents can cause physical disruption and financial loss. The priority is to prevent damage through risk assessment, appropriate safeguards and a tested response, not rely on compensation afterwards. Insurance is not a complete safety net: limitations in cybersecurity insurance coverage may leave losses uninsured, depending on policy terms and incident circumstances. Safeguards cannot guarantee that losses will be avoided, and insurance payments may not fully remedy reputational harm.
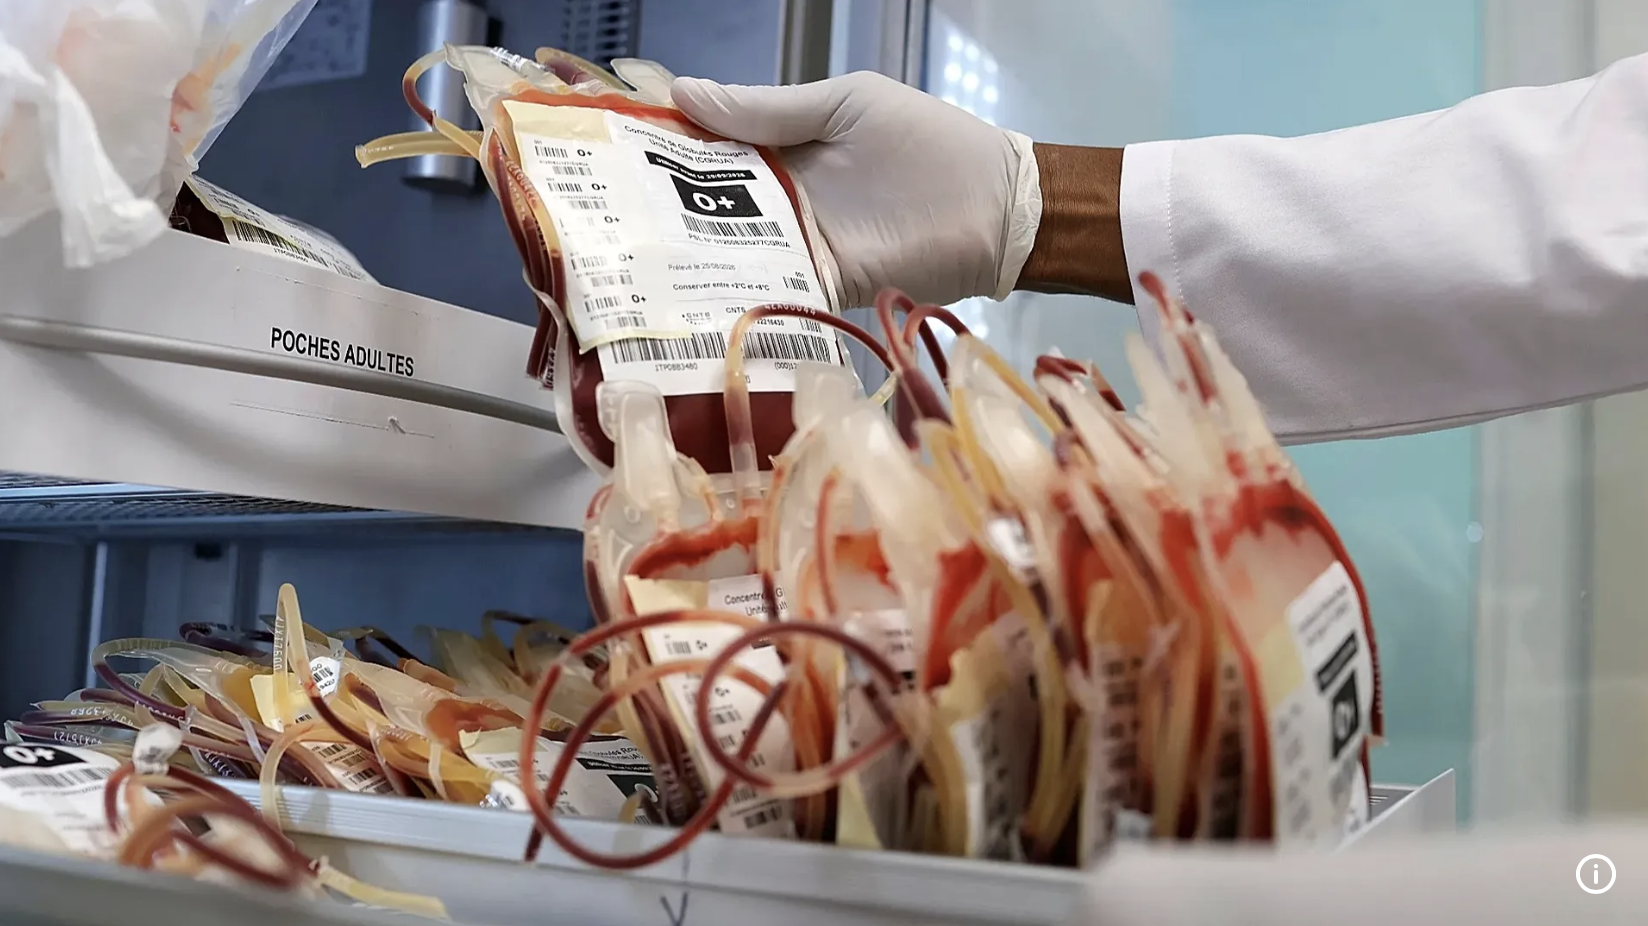
The lesson extends beyond one manufacturer, vulnerability or sector, but the consequences are not interchangeable. Retail and cold-logistics incidents may destroy replaceable stock and interrupt business, subject to the insurance limitations described above. In IVF, losing patient embryos can permanently remove a treatment opportunity; in biobanks, losing decades of longitudinal samples can erase research material that cannot be recreated. In blood banks, compromised transfusion-ready cellular products can jeopardise availability and timely patient care. These distinctions matter wherever connected hardware controls temperature, humidity, pressure, ventilation or gas concentrations, including laboratories, hospitals, pharmaceutical storage, cleanrooms and production environments. Leaders must assess scientific, clinical and operational consequences, together with loss of confidence among customers, patients and partners, rather than replacement cost alone.
IT leaders can use this paper to engage their C-suite, facilities director or risk audit committee in a discussion about exposure, ownership and evidence that safeguards work. Responsibility is shared, but outsourcing installation or maintenance does not transfer the asset owner’s operational risk. Manufacturers must deliver secure, supportable products; integrators must avoid unsafe architectures; and maintenance providers must control privileged remote access. Customers must know what is connected, assign clear security responsibilities and address unsupported equipment. These discussions should lead to agreed priorities, assigned actions and clear decisions on matters requiring management approval. Neglected safeguards belong on the leadership agenda as potential sources of uninsured loss and reputational damage, not merely as IT issues.
Even a well-secured primary system can fail, be misconfigured or become compromised. A risk inventory and assessment must identify critical processes, evaluate potential failures and their consequences, and define proportionate safeguards. For these processes, redundant, independent monitoring must measure physical conditions separately, apply independent alarm logic and support reliable notification, escalation and follow-up. Monitoring complements preventive cybersecurity; it does not replace a tested, facility-owned operational response. The objective is to create time to act before harmful deviations cause irreversible clinical, scientific, operational, financial or reputational loss.
Protect samples before loss becomes irreversible. Every laboratory holding valuable samples, not only pharmaceutical laboratories, needs a risk-based protection strategy. Identify potential failures and the consequences of sample loss, then combine prevention, redundant independent monitoring and a tested operational response. The purpose is not simply to raise an alarm, but to create time for people to act before samples are irreversibly damaged.
A cyber incident with physical consequences
Operational technology differs from conventional office IT because it controls physical conditions. A compromised control system can change a temperature, stop ventilation, suppress an alarm or activate a heating function. The consequences therefore extend beyond lost data or productivity: they can threaten products, irreplaceable samples, patient care, research and business continuity.
Remote management makes these systems easier to support. Engineers can diagnose faults, adjust settings and maintain installations across multiple locations without travelling. But that convenience also creates a route to powerful control functions. If an unauthorised person gains access to a supervisory controller, ordinary configuration tools may be enough to disrupt the process. The same access that enables efficient maintenance can therefore become a source of physical risk.
The European refrigeration incidents illustrate this risk: public reporting describes compromised remote controllers and changes to operating parameters. Authorities advised organisations to remove direct internet exposure, check the complete configuration and defrost schedules, update firmware, change default credentials and restore remote access only through a protected connection. The issue is not confined to commercial refrigeration; it also reaches services responsible for life-critical biological material.
The consequences also extend to blood services. In France, a cybersecurity incident affecting a refrigeration supplier altered temperature and defrost settings at blood-service cold stores. Monitoring and alarms enabled rapid intervention: products and samples were secured or transferred, with no reported blood-product losses or health impact. In the UK, the disruption arose elsewhere in the blood-service chain: a cyberattack on pathology services interrupted blood-transfusion testing and cross-matching, increasing reliance on O-type blood and contributing to a national shortage.
These incidents demonstrate different failure paths, not a single attack method or common perpetrator, but show why safeguarding blood services requires attention to both physical storage conditions and the digital services that support a safe supply. The shared lesson is that weaknesses in connected equipment, supplier access or supporting IT can disrupt operations. Operational resilience must therefore address the complete chain rather than one device or vendor.
A risk-based approach must also look beyond a single assumed motive. Relevant scenarios range from criminals seeking money through extortion to deliberate sabotage, including possible terrorist motives. Hybrid warfare is another scenario to consider: the Council of the European Union identifies cyberattacks and sabotage as elements of hybrid threats. These possibilities are not confirmed explanations for the incidents described here; attribution requires evidence. Whatever the motive, the operational requirement remains the same: secure access, detect harmful changes and maintain an effective response throughout the system’s lifecycle.
Security by design must remain secure in operation
Security by design is often discussed as a product-development principle. For control systems, it must extend much further. A secure product can still become unsafe when it is installed behind an open port, configured with shared credentials, left on outdated firmware or maintained through an uncontrolled remote-access route. Conversely, good network segmentation cannot permanently compensate for a controller that no longer receives security updates.
The IEC 62443 series provides a framework for securing industrial automation and control systems. It connects product security, system architecture and operational responsibilities within a shared-responsibility approach. Manufacturers, integrators, service providers and asset owners must each manage the risks within their control and coordinate protection throughout the operational life of the installation. The framework is therefore not simply a set of network measures to apply after installation: its principles must inform product design and remain part of integration, operation and ongoing support.
For internet-facing or remotely accessible control systems, security must begin in the product-design phase, not be added after installation. Neglecting relevant IEC 62443 principles can embed weaknesses in authentication, privilege separation, input handling and update mechanisms that network segmentation or careful operation alone cannot reliably resolve. Design must establish strong authentication without default, shared or predictable secrets, separate configuration authority from read-only monitoring, make important changes traceable to an individual user and provide secure firmware updates with transparent support periods. These protections must be maintained through integration, commissioning and ongoing operation. Applying IEC 62443 principles though does not guarantee a flaw-free product. Remote management must use protected access routes rather than direct public internet exposure, with remaining risks documented and assessed.
Zones and conduits: controlling trust boundaries
IEC 62443 groups assets with common security requirements into zones, linked through controlled conduits. An illustrative architecture separates a sensor zone for measurement and acquisition, a control-system zone for controllers and actuators, and an operational-system zone for supervisory applications and operator interfaces. Office IT and external maintenance access can occupy separate zones. Conduits define permitted sources, destinations, protocols and communication direction, enforced through gateways, firewalls or other boundary controls. Measurement, supervisory and maintenance connections must not provide unrestricted control access. Diagrams and VLAN labels alone offer no protection: boundaries must restrict traffic. Segmentation limits exposure and the spread of compromise, but neither repairs vulnerable controllers nor establishes monitoring independence. See Security Aspects of Zones and Conduits in IEC 62443.
Authentication bypass and unsafe input handling are product-security flaws
The refrigeration incidents demonstrate the physical consequences of unauthorised control. Separate vulnerability research has documented authentication bypass and command injection: product-security defects in affected versions, not merely deployment mistakes. Bypassing authentication defeats identity controls; allowing untrusted input to become executable commands exposes unsafe input handling. Manufacturers must correct these flaws; segmentation cannot replace secure products. Protection requires authentication and authorisation on every privileged access path, server-side input validation and separation of data from executable instructions. The research establishes design or implementation defects, not the exploitation route in each attack. Updated firmware, controlled access and verified safeguards remain necessary.
Midnight Blue’s November 2026 research reinforces this distinction: researchers reported multiple vulnerabilities allowing remote code execution without authentication in refrigeration controllers, including the latest firmware they assessed at the time. Updating firmware or changing passwords alone therefore cannot establish that an exposed system is secure. Direct internet exposure must be removed without waiting for patches, while available security updates remain part of controlled lifecycle maintenance. These findings strengthen the case for secure product design and restricted remote access.
From framework to lifecycle: maintaining protection at every stage
These principles make a lifecycle model necessary: secure design establishes the foundation, but protection can be weakened by installation choices, configuration changes, remote access or the end of security support. A credible security model must therefore cover Product Design, Integration, Verification & Validation, Commissioning, Remote Support, Patching & Updates, Incident Response, Eventual Replacement. These activities are connected responsibilities, not a one-off checklist completed at handover. Across the full lifecycle, basic IT security principles, clear ownership and coordinated safeguards must remain in place so that the installation stays secure, supportable and manageable as conditions change.
Figure 1: Control system lifecycle security model.
Where organisations fail, and what it costs
The manufacturer: functionality without a secure lifecycle
A manufacturer creates the first line of defence. The weakness begins when remote serviceability is prioritised over secure architecture, or when a device contains undocumented access mechanisms, weak identity controls or insufficient logging. It also arises when updates are difficult to deploy or when support ends without a realistic migration path.
The consequence can scale far beyond one device. A supervisory controller may manage many connected assets, and a common product is often deployed in the same way across many sites. One weakness can therefore become repeatable. Manufacturers must be judged not only on whether the equipment performs today, but on whether it can remain secure, updatable and supportable throughout its expected operational life.
Manufacturers carry a particular responsibility because customers may not recognise when convenience, cost savings or weak defaults conceal security shortcuts. A customer’s lack of technical expertise must not become an excuse for insecure design or unclear support commitments. The EU Cyber Resilience Act (CRA), Regulation (EU) 2024/2847, places responsibility on manufacturers of products within its scope for risk assessment, security by design and by default, clear user instructions, a declared support period and vulnerability handling during that period. This reinforces the principle that customers should not have to discover hidden weaknesses before manufacturers address them. The main CRA obligations apply from 11 December 2027, while reporting obligations have applied since 11 September 2026. Applicability must be checked for each product, including relevant exclusions; the CRA does not remove the customer’s responsibility for secure operation.
The asset owner: keeping equipment because it still works
Working equipment is not necessarily secure. A controller may regulate temperature correctly while its security model is obsolete. For networked equipment affecting critical processes, the end of security support must trigger replacement, isolation or a formally approved short-term exception with compensating controls.
“This has worked for me for the last twenty years. Why should we change a working solution?” This illustrative objection confuses past reliability with present protection. Equipment may remain unchanged while threats evolve rapidly. Retention must depend on whether connectivity, support and safeguards remain fit for purpose, supported by a documented risk decision, not longevity alone.
The consequences of delay cannot be measured by an inventory write-off alone. Retail stock may be replaceable, although business interruption and insurance gaps remain. Patient embryos and unique longitudinal biobank samples may not be replaceable at all. Loss of usable blood components can interrupt timely transfusion care. Asset owners must therefore assess irreversible loss, treatment disruption and scientific consequences, not merely the asset-register value or potential insurance payment.
The integrator: turning remote service into public exposure
Manufacturers and integrators may be one organisation or separate companies. Either way, both responsibilities apply: explain product-security capabilities and limitations, and deliver a secure installation. Separate suppliers add interfaces and handovers; neither party may assume the other owns an unresolved risk.
Public exposure, broad port forwarding, reused passwords and undocumented firewall rules can undermine a capable product. Handover must document architecture, data flows, permissions, security configuration, logging, patch ownership and safe isolation, making access and change authority clear to the customer.
From design through operation, the integrator and customer’s internal or external IT provider must agree segmentation, protected remote access, individual accounts, approvals, logging, monitoring and incident-response integration. Controls must protect cybersecurity without disrupting critical operations.
After handover, the customer, integrator and IT provider must maintain documentation and ownership of changes, updates, access reviews, recovery and replacement, involving the manufacturer when needed. Equipment or IT-environment changes must trigger coordinated review to preserve lifecycle security and supportability.
The maintenance provider: remote access without equivalent accountability
Remote maintenance grants privileged access to physical processes. Engineers may know the equipment without being cybersecurity specialists, so providers must make secure working practical through accessible tools, training and procedures. Controls must protect installations without obstructing routine maintenance or urgent intervention.
Use named accounts, strong authentication, defined permissions and logged sessions. Plan controlled emergency access rather than bypassing safeguards. With the customer’s IT provider, ensure access can be granted, reviewed and revoked efficiently, including for subcontractors. Security must reduce overall risk without creating greater operational problems.
For organisations within NIS2’s scope, third-party maintenance access is also a supply-chain compliance issue. Article 21 requires cybersecurity risk management to address direct suppliers and service providers, access controls and the effectiveness of protective measures. Uncontrolled or unmonitored remote access can therefore represent a serious compliance gap, subject to applicable national law and the organisation’s risk profile. Maintenance contracts should define access approval, authentication, logging, monitoring, revocation and incident responsibilities, with evidence that these controls operate in practice.
Internal IT, facilities and management: gaps between responsibilities
Connected refrigeration, HVAC and laboratory equipment spans IT, facilities, quality and operations. Staff may understand its purpose but miss network dependencies, remote-access risks or support requirements. When IT sees facilities equipment, facilities trusts the supplier and quality focuses on compliance, essential safeguards can lack an end-to-end owner.
Management must assign ownership and unite internal teams and providers around shared risk management, clear dependencies and escalation routes. Outsourcing tasks does not transfer operational-risk accountability. Unsupported equipment, unclear ownership and unverified supplier access must remain visible, with replacement and independent-monitoring decisions reflecting failure consequences, not just likelihood or purchase price.
Figure 2: Relationships and shared responsibilities between all stakeholders.
Managing increasingly complex supplier coordination
As more stakeholders become involved, implementing and maintaining a reliable solution becomes a greater coordination challenge. Each additional party introduces interfaces, dependencies, approval steps and potential gaps in responsibility. A change that is straightforward within one organisation may require agreement across several suppliers, slowing the response when global conditions, threats or operational requirements change rapidly. A solution must therefore be judged not only on whether its individual components work, but on whether the complete chain can be managed, tested and adapted within the time available.
Organisations should therefore consider reducing unnecessary supplier handovers and selecting solution providers capable of coordinating the operational resilience chain end to end, rather than managing isolated components. Within a clearly defined contractual scope, the provider should take responsibility for delivering and maintaining the agreed safeguards across design, integration, monitoring, maintenance, escalation and recovery. The customer retains accountability for risk acceptance, operational decisions and the human response. The aim is fewer gaps between these activities, with clear authority to coordinate changes quickly.
This does not mean excluding essential stakeholders or assuming that a single supplier removes all risk. Supplier consolidation and monitoring independence address different issues: fewer handovers can simplify coordination, while separate measurement, alarm evaluation and appropriately independent power and communication arrangements reduce shared failure risks. Any consolidated solution must demonstrate that independence, preserve transparent responsibilities and customer oversight, and include a credible continuity and exit plan. The objective is a simpler, more accountable arrangement that remains dependable in daily operation and adaptable when circumstances change.
Why prevention alone is not enough
Good cybersecurity reduces the chance of compromise, but it cannot guarantee that compromise will never occur. Credentials can be stolen, a trusted supplier can be breached, a configuration error can expose a system and a legitimate engineer can make a harmful change. New vulnerabilities may exist before a patch is available. Even a secure update can produce an unexpected operational effect.
Resilient design therefore considers two questions at the same time. How do we prevent unauthorised access? And how do we detect the physical consequence if access, configuration or control nevertheless goes wrong? The first question belongs to preventive security. The second requires an independent source of truth.
A critical distinction. An alarm generated by the same controller that is being manipulated is not a fully independent protection layer. Real independence requires separate measurement, separate evaluation and, where appropriate, a separate power supply & communication route.
Independent monitoring as a second source of truth
Control path and independent monitoring path, side by side.
Independent monitoring provides a second source of truth by measuring physical conditions separately from the primary controller and applying independently managed alarm limits. The French blood-service incident described earlier demonstrates the practical value of monitoring, alarms and timely intervention: products and samples were secured or transferred, with no reported blood-product losses or health impact. That outcome supports the case for effective warning, but does not by itself establish the architectural independence or redundancy of the systems involved.
Effective monitoring must remain available during the failures it is intended to reveal. A larger incident may interrupt internet connectivity or power across an entire facility, potentially disabling both primary equipment and its alarm chain. Independent monitoring therefore needs sufficient redundancy to preserve warning and escalation under the disruption scenarios identified in the risk assessment. It cannot prevent the initial attack or keep the controlled equipment running by itself.
Redundancy must extend through the complete monitoring chain, not stop at an additional sensor or dashboard. Risk assessment must define the disruption scenarios and duration of autonomous operation the system is designed to withstand, together with the arrangements needed to sustain measurement, local alarm evaluation, data buffering, backup power and alternative communication routes. A fallback route must not rely on the same connection or power source whose failure it is meant to cover. The same secure-design and lifecycle-management principles apply: the system must be maintained, updated and tested, including exercises that remove normal power and internet access and verify that alarms still reach people able to act. These measures create an opportunity for timely intervention; they do not guarantee that every loss can be prevented. Any remaining limitations must be understood and accepted through the risk-assessment process.
A more mature operating model
A mature operating model starts with a thorough risk inventory and assessment, not with the purchase of equipment or the assumption that existing safeguards are sufficient. Organisations must identify critical processes, valuable samples and connected assets; understand their dependencies on power, networks and suppliers; and assess the consequences of failure or compromise. The assessment must establish which risks require action, who owns them and what level of protection and continuity is needed. It provides the basis for decisions on secure connectivity, equipment replacement, independent monitoring and human response.
Where customers lack the expertise, resources or capacity to carry out this work themselves, they should engage a specialist company with a demonstrable track record and the capability to assess their operational environment. Selection should be based on relevant experience, a clear assessment method and evidence that the provider can translate findings into practical, manageable safeguards, not simply recommend products. The work must involve the customer’s operational, IT, facilities and quality teams so that technical dependencies and the consequences of sample or service loss are understood together. External support strengthens the assessment; it does not transfer the customer’s accountability for accepting and managing risk.
The result must be a documented, prioritised action plan with clear responsibilities, agreed timescales and funding. It should address remote exposure, access controls, firmware and support status, supplier responsibilities, safe isolation and the independence and redundancy of monitoring. Safeguards must then be verified through alarm-chain tests, out-of-hours response exercises and checks under loss of normal power or connectivity. Risk inventory and assessment are ongoing responsibilities: they must be reviewed when equipment, suppliers, connectivity or threats change, so that protection remains aligned with the actual operating environment.
XiltriX Resilience supports operational resilience
XiltriX Resilience is designed to support operational resilience by providing an independent monitoring layer across mission-critical environments. Its contribution combines physical infrastructure, monitoring intelligence and ongoing care rather than relying on a single sensor or software feature. These elements support detection, notification and follow-up, but effective protection also depends on the customer’s primary-system security, risk decisions and human response. Technology and service must work together within that shared-responsibility model.
Infrastructure: measuring the physical reality
Dedicated monitoring stations and sensors create a measurement path outside the primary control logic. Depending on the application, this may include temperature, humidity, differential pressure, oxygen, carbon dioxide, door status, equipment alarm contacts, power status and communication health. Local buffering and battery-supported operation help preserve evidence and visibility during disruptions.
From physical measurement to the right response
-
Independent sensors measure incubators, refrigerators, room conditions and cryogenic storage.
-
Dedicated monitoring stations provide local buffering and battery-supported operation.
-
Secure cloud hosting supports monitoring data, SSO and the REST API.
-
Environmental deviations follow the customer-defined notification and escalation route to the facility team.
-
Monitoring-system faults go to XiltriX technical support; 24/7 remote technical support belongs to Intelligence.
Figure 3: The XiltriX Resilience capabilities (www.xiltrix.com)
Intelligence: detecting and communicating what matters
The software layer continuously evaluates measurements, manages alarm thresholds and provides dashboards, notifications, escalation, incident reporting and compliance evidence. Remote diagnostics and system-health monitoring help distinguish environmental deviations from sensor, power or communication problems. The monitoring platform also requires secure cloud hosting and ongoing software lifecycle management so that it remains supported rather than becoming an unmanaged legacy system.
Intelligence includes software and OTA firmware updates and 24/7 remote technical support for the monitoring system itself. The customer remains responsible for responding to environmental and equipment alarms.
Care: on-site services
Care covers on-site services: installation by partners supported by XiltriX, commissioning, validation, training, calibration and maintenance.
Technical monitoring responsibilities and customer response
XiltriX is responsible for the technical monitoring chain, including measurement, data recording, alarm generation and technical notification delivery within the agreed service scope. Monitoring-system faults are handled by XiltriX technical support. The facility or client team remains responsible for maintaining alarm contacts and response procedures, acknowledging operational alarms, assessing their significance and taking timely action to protect samples, products and patients. Technical alarm delivery does not constitute operational intervention.
Does XiltriX monitoring add an attack surface?
XiltriX’s monitoring configuration separates measurement from control: Pt1000 sensors, 4–20 mA signals and dry-contact inputs capture physical conditions independently of the primary control loop or PLCs. In this configuration, no actuator or controller-write connection is provided: monitoring cannot remotely change setpoints or shut down chillers. Encrypted telemetry uses outbound-initiated connections, requiring no inbound firewall ports or port forwarding. Deployment options include a dedicated, firewall-segmented VLAN or a cellular-only path separate from the facility network, not a true air gap. The customer’s IT/security team must verify the deployed data flows, isolation and absence of control paths before approval.
Important Note. XiltriX Resilience should not be positioned as a reason to tolerate an insecure primary controller. It is a defence-in-depth layer that reduces reliance on any one controller, network, communication path or service organisation. The primary environment must still be secured, patched and replaced when support ends.
Questions leaders should be able to answer
Leaders in every business need to be “In Control”, not only those in pharmaceutical or other highly regulated environments. This means understanding the risks the organisation runs, the consequences of failure and the mitigation options available to reduce those risks. It does not require mastery of every technical detail or the elimination of all risk. It requires a current risk inventory and assessment, informed decisions on proportionate safeguards, clear ownership and evidence that those safeguards work. Leaders must understand the risk remaining after mitigation and explicitly decide whether it is acceptable.
The Know, Reach, Act test: If the primary controller were compromised and normal power and internet access failed, would we know the physical conditions independently, reach an accountable person and act before irreversible damage? A pass requires demonstrated independent measurement, a tested notification and escalation route, and a facility-owned response completed within the time available under the assessed scenario. An alarm alone is not a pass.
The essential questions are practical: which connected systems can affect a critical process, and who can access them? Is access individually authenticated and logged? When does security support end, and can equipment be isolated safely? What happens if power, internet connectivity or a key supplier becomes unavailable? Which preventive controls, independent monitoring and recovery arrangements can limit the consequences, and who responds outside normal working hours? Where expertise is lacking, leaders should obtain qualified support while retaining oversight. Being “In Control” means being able to explain these choices and demonstrate follow-through, not simply assuming that IT or a supplier has taken care of everything.
European cybersecurity legislation gives this accountability a legal dimension for organisations within its scope. Article 20 of the NIS2 Directive requires Member States to ensure that management bodies of essential and important entities approve cybersecurity risk-management measures, oversee their implementation and can be held liable for infringements of those duties. It also requires management-body members to undertake training. The applicable obligations and liability mechanisms must be checked against national implementing law; these provisions do not apply indiscriminately to every business.
The Cyber Resilience Act (CRA), Regulation (EU) 2024/2847, separately establishes product-security responsibilities for manufacturers of products within its scope, including risk assessment, security by design and by default, and vulnerability handling during the declared support period. Leaders of affected manufacturers must ensure their organisations can discharge these responsibilities; the CRA should not be presented as imposing the same personal management-liability regime as NIS2. CRA reporting obligations have applied since 11 September 2026; its main obligations apply from 11 December 2027. Leaders should establish which rules apply to their organisation and products and obtain legal advice where necessary. The broader management principle remains relevant to every business: understand the exposure, choose appropriate mitigations and retain evidence of informed oversight.
Conclusion
The European refrigeration incidents are not a reason to wait for the next warning. They expose how remote access, legacy equipment and fragmented responsibility can turn a digital compromise into physical loss. The pressure is expected to intensify: the UK National Cyber Security Centre assesses that AI will almost certainly increase the frequency and intensity of cyber threats, with the volume and impact of intrusions highly likely to rise through 2027. As attacks become more frequent and efficient, organisations risk being outpaced by the effort required to detect, coordinate and respond. Relying on people to react faster after every incident is not a sustainable protection strategy.
Leaders in every business must be “In Control” before an incident begins. That requires a current risk inventory and assessment, explicit decisions on mitigation and clear accountability across manufacturers, integrators, maintenance providers and internal teams. Unsupported equipment and unclear supplier access must be addressed, not tolerated because the installation still works. Where expertise is missing, qualified support must be brought in. The objective is to reduce exposure and remove avoidable delays before a harmful change demands an urgent response.
Even then, prevention cannot be the only barrier between an attack and irreversible damage. Independent monitoring is the last line of defence for detecting harmful physical changes, and its power, communications and escalation arrangements must withstand the failures it is intended to reveal. Those arrangements must be tested alongside the people authorised to act. As attack pressure grows, every avoidable delay consumes time that may be needed to protect samples, products and services. Resilience must be designed, maintained and rehearsed in advance: once physical damage begins, there may be no second chance.
Final thought. Operational resilience starts with the assumption that failures will happen. It requires tested mitigation measures designed to detect problems early, limit their consequences and create time to act before irreversible damage occurs. Those safeguards must remain adaptable as global conditions, threats and operational demands change rapidly.
References
-
Wikipedia, Operational technology (background definition). Accessed 5 November 2026.
-
CERT-FR, CERTFR-2026-ALE-012, Incident de sécurité ciblant les contrôleurs à distance des installations de réfrigération, 12 October 2026, updated 16 October 2026. Accessed 18 November 2026.
-
EN IEC 62443 series: Part 4-1, Secure product development lifecycle requirements; Part 2-4, Security program requirements for IACS service providers; and Part 3-3, System security requirements and security levels. Supporting overview: NEN, IEC 62443: Industriële cybersecurity. Accessed 5 November 2026.
-
Directive (EU) 2022/2555 (NIS2), Articles 20–21: governance and cybersecurity risk-management measures. Accessed 5 November 2026.
-
European Commission, Cyber Resilience Act – Manufacturers and Cyber Resilience Act: application timetable. Accessed 5 November 2026.
-
UK National Cyber Security Centre, Impact of AI on cyber threat from now to 2027, 2025. Accessed 5 November 2026.
-
Établissement français du sang (EFS), statement on the cybersecurity incident affecting a refrigeration-equipment supplier, November 2026. Accessed 5 November 2026.
-
NHS England – London, Latest media statement on Synnovis cyber-attack. Accessed 5 November 2026.
-
Council of the European Union, Hybrid threats. Accessed 5 November 2026.
-
NIS2 Info, NIS2 Directive: Article 20 – Governance (secondary reproduction of the provision; the official Directive is listed above). Accessed 5 November 2026.
-
NU.nl, report on refrigeration cyberattacks and insurance coverage for spoiled stock (linked in the Executive summary).
-
XiltriX International, company website (linked in Figure 3).
-
Jaatun et al., Security Aspects of Zones and Conduits in IEC 62443, Journal of Cybersecurity and Privacy, 2026, 6(2), 52. Accessed 18 November 2026.
-
Claroty Team82, Freeze the Controller, Defrost the Food: Uncovering Vulnerabilities in Danfoss Refrigeration Controllers, 9 August 2026. Accessed 18 November 2026.
-
Claroty, How to Find and Secure Internet-Exposed Cooling Controllers Across Multi-Site Facilities, 4 November 2026. Accessed 18 November 2026.
-
Midnight Blue, research on multiple pre-authentication remote code execution vulnerabilities in refrigeration controllers, November 2026. Accessed 18 November 2026.
-
Centre for Cybersecurity Belgium, advisory on six newly reported refrigeration-controller vulnerabilities and immediate exposure reduction, 12 November 2026. Accessed 18 November 2026.